Remote VAEs for decoding with Inference Endpoints 🤗
(This post was authored by hlky and Sayak)
When operating with latent-space diffusion models for high-resolution image and video synthesis, the VAE decoder can consume quite a bit more memory. This makes it hard for the users to run these models on consumer GPUs without going through latency sacrifices and others alike.
For example, with offloading, there is a device transfer overhead, causing delays in the overall inference latency. Tiling is another solution that lets us operate on so-called “tiles” of inputs. However, it can have a negative impact on the quality of the final image.
Therefore, we want to pilot an idea with the community — delegating the decoding process to a remote endpoint.
No data is stored or tracked, and code is open source. We made some changes to huggingface-inference-toolkit and use custom handlers.
This experimental feature is developed by Diffusers 🧨
Table of contents:
Code
Basic example
Options
Generation
Queueing
Getting started
Below, we cover three use cases where we think this remote VAE inference would be beneficial.
Code
First, we have created a helper method for interacting with Remote VAEs.
Install
diffusersfrommainto run the code.pip install git+https://github.com/huggingface/diffusers@main
Code
from diffusers.utils.remote_utils import remote_decodeBasic example
Here, we show how to use the remote VAE on random tensors.
Code
image = remote_decode(
    endpoint="https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud/",
    tensor=torch.randn([1, 4, 64, 64], dtype=torch.float16),
    scaling_factor=0.18215,
)
Usage for Flux is slightly different. Flux latents are packed so we need to send the height and width.
Code
image = remote_decode(
    endpoint="https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud/",
    tensor=torch.randn([1, 4096, 64], dtype=torch.float16),
    height=1024,
    width=1024,
    scaling_factor=0.3611,
    shift_factor=0.1159,
)
Finally, an example for HunyuanVideo.
Code
video = remote_decode(
    endpoint="https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud/",
    tensor=torch.randn([1, 16, 3, 40, 64], dtype=torch.float16),
    output_type="mp4",
)
with open("video.mp4", "wb") as f:
    f.write(video)
Generation
But we want to use the VAE on an actual pipeline to get an actual image, not random noise. The example below shows how to do it with SD v1.5.
Code
from diffusers import StableDiffusionPipeline

pipe = StableDiffusionPipeline.from_pretrained(
    "stable-diffusion-v1-5/stable-diffusion-v1-5",
    torch_dtype=torch.float16,
    variant="fp16",
    vae=None,
).to("cuda")

prompt = "Strawberry ice cream, in a stylish modern glass, coconut, splashing milk cream and honey, in a gradient purple background, fluid motion, dynamic movement, cinematic lighting, Mysterious"

latent = pipe(
    prompt=prompt,
    output_type="latent",
).images
image = remote_decode(
    endpoint="https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud/",
    tensor=latent,
    scaling_factor=0.18215,
)
image.save("test.jpg")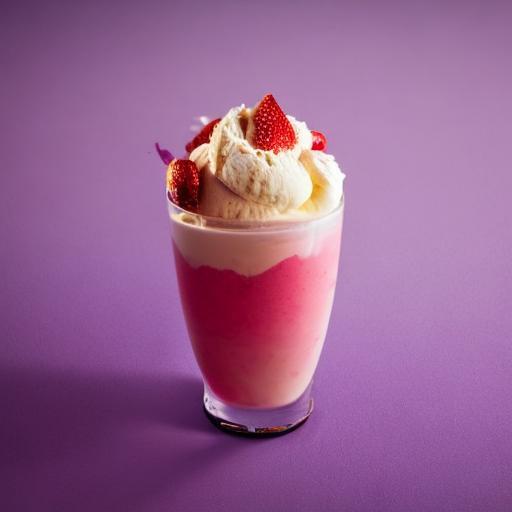
Here’s another example with Flux.
Code
from diffusers import FluxPipeline

pipe = FluxPipeline.from_pretrained(
    "black-forest-labs/FLUX.1-schnell",
    torch_dtype=torch.bfloat16,
    vae=None,
).to("cuda")

prompt = "Strawberry ice cream, in a stylish modern glass, coconut, splashing milk cream and honey, in a gradient purple background, fluid motion, dynamic movement, cinematic lighting, Mysterious"

latent = pipe(
    prompt=prompt,
    guidance_scale=0.0,
    num_inference_steps=4,
    output_type="latent",
).images
image = remote_decode(
    endpoint="https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud/",
    tensor=latent,
    height=1024,
    width=1024,
    scaling_factor=0.3611,
    shift_factor=0.1159,
)
image.save("test.jpg")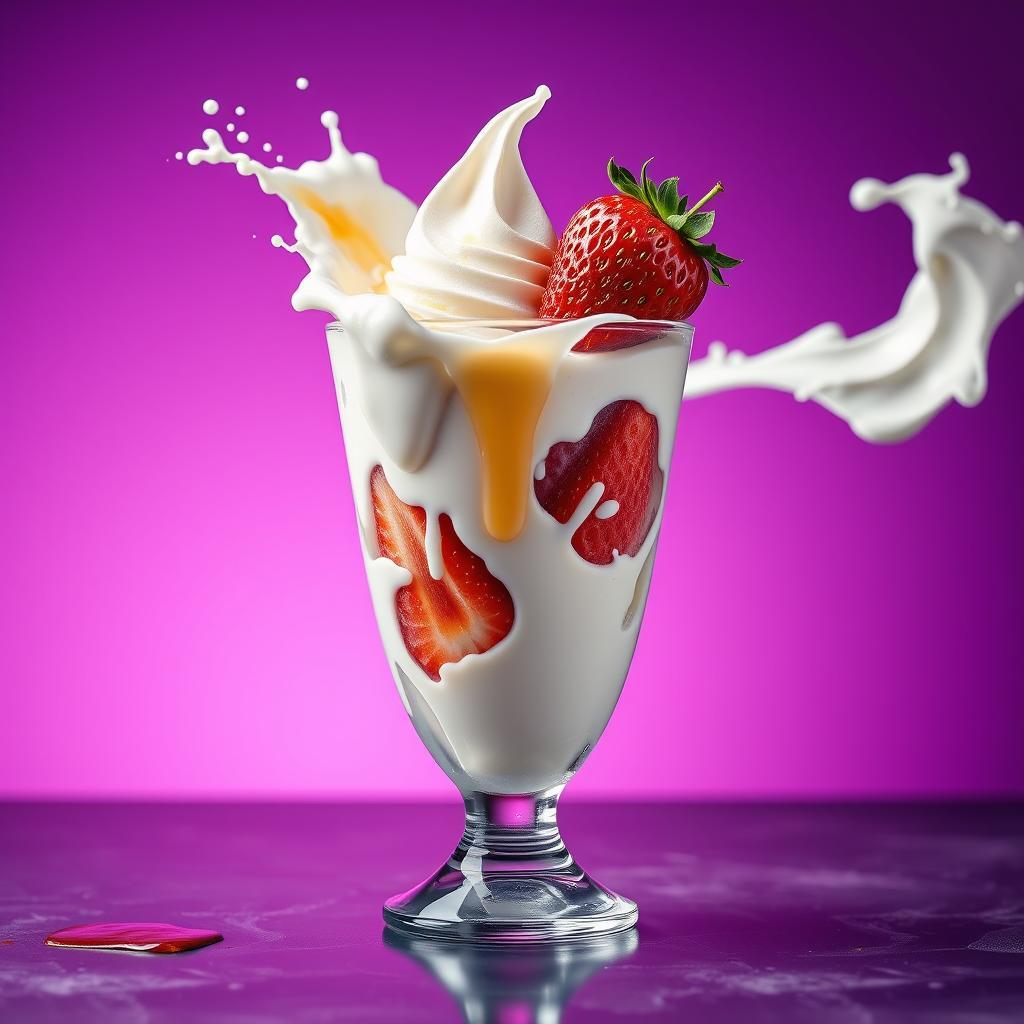
Here’s an example with HunyuanVideo.
Code
from diffusers import HunyuanVideoPipeline, HunyuanVideoTransformer3DModel

model_id = "hunyuanvideo-community/HunyuanVideo"
transformer = HunyuanVideoTransformer3DModel.from_pretrained(
    model_id, subfolder="transformer", torch_dtype=torch.bfloat16
)
pipe = HunyuanVideoPipeline.from_pretrained(
    model_id, transformer=transformer, vae=None, torch_dtype=torch.float16
).to("cuda")

latent = pipe(
    prompt="A cat walks on the grass, realistic",
    height=320,
    width=512,
    num_frames=61,
    num_inference_steps=30,
    output_type="latent",
).frames

video = remote_decode(
    endpoint="https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud/",
    tensor=latent,
    output_type="mp4",
)

if isinstance(video, bytes):
    with open("video.mp4", "wb") as f:
        f.write(video)
Queueing
One of the great benefits of using a remote VAE is that we can queue multiple generation requests. While the current latent is being processed for decoding, we can already queue another one. This helps improve concurrency.
Code
import queue
import threading
from IPython.display import display
from diffusers import StableDiffusionPipeline

def decode_worker(q: queue.Queue):
    while True:
        item = q.get()
        if item is None:
            break
        image = remote_decode(
            endpoint="https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud/",
            tensor=item,
            scaling_factor=0.18215,
        )
        display(image)
        q.task_done()

q = queue.Queue()
thread = threading.Thread(target=decode_worker, args=(q,), daemon=True)
thread.start()

def decode(latent: torch.Tensor):
    q.put(latent)

prompts = [
    "Blueberry ice cream, in a stylish modern glass , ice cubes, nuts, mint leaves, splashing milk cream, in a gradient purple background, fluid motion, dynamic movement, cinematic lighting, Mysterious",
    "Lemonade in a glass, mint leaves, in an aqua and white background, flowers, ice cubes, halo, fluid motion, dynamic movement, soft lighting, digital painting, rule of thirds composition, Art by Greg rutkowski, Coby whitmore",
    "Comic book art, beautiful, vintage, pastel neon colors, extremely detailed pupils, delicate features, light on face, slight smile, Artgerm, Mary Blair, Edmund Dulac, long dark locks, bangs, glowing, fashionable style, fairytale ambience, hot pink.",
    "Masterpiece, vanilla cone ice cream garnished with chocolate syrup, crushed nuts, choco flakes, in a brown background, gold, cinematic lighting, Art by WLOP",
    "A bowl of milk, falling cornflakes, berries, blueberries, in a white background, soft lighting, intricate details, rule of thirds, octane render, volumetric lighting",
    "Cold Coffee with cream, crushed almonds, in a glass, choco flakes, ice cubes, wet, in a wooden background, cinematic lighting, hyper realistic painting, art by Carne Griffiths, octane render, volumetric lighting, fluid motion, dynamic movement, muted colors,",
]

pipe = StableDiffusionPipeline.from_pretrained(
    "Lykon/dreamshaper-8",
    torch_dtype=torch.float16,
    vae=None,
).to("cuda")

pipe.unet = pipe.unet.to(memory_format=torch.channels_last)
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)

_ = pipe(
    prompt=prompts[0],
    output_type="latent",
)

for prompt in prompts:
    latent = pipe(
        prompt=prompt,
        output_type="latent",
    ).images
    decode(latent)

q.put(None)
thread.join()
Available VAEs
Endpoint
Model
Stable Diffusion v1
https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud
Stable Diffusion XL
https://x2dmsqunjd6k9prw.us-east-1.aws.endpoints.huggingface.cloud
Flux
https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud
black-forest-labs/FLUX.1-schnell
HunyuanVideo
https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud
hunyuanvideo-community/HunyuanVideo
Advantages of using a remote VAE
These tables demonstrate the VRAM requirements with different GPUs. Memory usage % determines whether users of a certain GPU will need to offload. Offload times vary with CPU, RAM and HDD/NVMe. Tiled decoding increases inference time.
SD v1.5
GPU
Resolution
Time (seconds)
Memory (%)
Tiled Time (secs)
Tiled Memory (%)
NVIDIA GeForce RTX 4090
512x512
0.031
5.60%
0.031 (0%)
5.60%
NVIDIA GeForce RTX 4090
1024x1024
0.148
20.00%
0.301 (+103%)
5.60%
NVIDIA GeForce RTX 4080
512x512
0.05
8.40%
0.050 (0%)
8.40%
NVIDIA GeForce RTX 4080
1024x1024
0.224
30.00%
0.356 (+59%)
8.40%
NVIDIA GeForce RTX 4070 Ti
512x512
0.066
11.30%
0.066 (0%)
11.30%
NVIDIA GeForce RTX 4070 Ti
1024x1024
0.284
40.50%
0.454 (+60%)
11.40%
NVIDIA GeForce RTX 3090
512x512
0.062
5.20%
0.062 (0%)
5.20%
NVIDIA GeForce RTX 3090
1024x1024
0.253
18.50%
0.464 (+83%)
5.20%
NVIDIA GeForce RTX 3080
512x512
0.07
12.80%
0.070 (0%)
12.80%
NVIDIA GeForce RTX 3080
1024x1024
0.286
45.30%
0.466 (+63%)
12.90%
NVIDIA GeForce RTX 3070
512x512
0.102
15.90%
0.102 (0%)
15.90%
NVIDIA GeForce RTX 3070
1024x1024
0.421
56.30%
0.746 (+77%)
16.00%
SDXL
GPU
Resolution
Time (seconds)
Memory Consumed (%)
Tiled Time (seconds)
Tiled Memory (%)
NVIDIA GeForce RTX 4090
512x512
0.057
10.00%
0.057 (0%)
10.00%
NVIDIA GeForce RTX 4090
1024x1024
0.256
35.50%
0.257 (+0.4%)
35.50%
NVIDIA GeForce RTX 4080
512x512
0.092
15.00%
0.092 (0%)
15.00%
NVIDIA GeForce RTX 4080
1024x1024
0.406
53.30%
0.406 (0%)
53.30%
NVIDIA GeForce RTX 4070 Ti
512x512
0.121
20.20%
0.120 (-0.8%)
20.20%
NVIDIA GeForce RTX 4070 Ti
1024x1024
0.519
72.00%
0.519 (0%)
72.00%
NVIDIA GeForce RTX 3090
512x512
0.107
10.50%
0.107 (0%)
10.50%
NVIDIA GeForce RTX 3090
1024x1024
0.459
38.00%
0.460 (+0.2%)
38.00%
NVIDIA GeForce RTX 3080
512x512
0.121
25.60%
0.121 (0%)
25.60%
NVIDIA GeForce RTX 3080
1024x1024
0.524
93.00%
0.524 (0%)
93.00%
NVIDIA GeForce RTX 3070
512x512
0.183
31.80%
0.183 (0%)
31.80%
NVIDIA GeForce RTX 3070
1024x1024
0.794
96.40%
0.794 (0%)
96.40%
Provide feedback
If you like the idea and feature, please help us with your feedback on how we can make this better and whether you’d be interested in having this kind of feature more natively integrated into the Hugging Face ecosystem. If this pilot goes well, we plan on creating optimized VAE endpoints for more models, including the ones that can generate high-resolution videos!
Steps:
Open an issue on Diffusers through this link.
Answer the questions and provide any extra info you want.
Hit submit!