LeRobot goes to driving school: World’s largest open-source self-driving dataset
TL;DR of L2D, the world's largest self-driving dataset!
90+ TeraBytes of multimodal data (5000+ hours of driving) from 30 cities in Germany
6x surrounding HD cameras and complete vehicle state: Speed/Heading/GPS/IMU
Continuous: Gas/Brake/Steering and discrete actions: Gear/Turn Signals
Environment state: Lane count, Road type (highway|residential), Road surface (asphalt, cobbled, sett), Max speed limit.
Environment conditions: Precipitation, Conditions (Snow, Clear, Rain), Lighting (Dawn, Day, Dusk)
Designed for training end-to-end models conditioned on natural language instructions or future waypoints
Natural language instructions. F.ex "When the light turns green, drive over the tram tracks and then through the roundabout" for each episode
Future waypoints snapped to OpenStreetMap graph, aditionally rendered in birds-eye-view
Expert (driving instructors) and student (learner drivers) policies
State-of-the art Vision Language Models and Large Language Models are trained on open-source image-text corpora sourced from the internet, which spearheaded the recent acceleration of open-source AI. Despite these breakthroughs, the adoption of end-to-end AI within the robotics and automotive community remains low, primarily due to a lack of high quality, large scale multimodal datasets like OXE. To unlock the potential for robotics AI, Yaak teamed up with the LeRobot team at 🤗 and is excited to announce Learning to Drive (L2D) to the robotics AI community. L2D is the world’s largest multimodal dataset aimed at building an open-sourced spatial intelligence for the automotive domain with first class support for 🤗’s LeRobot training pipeline and models. Drawing inspiration from the best practices of source version control, Yaak also invites the AI community to search and discover novel episodes in our entire dataset (> 1 PetaBytes), and queue their collection for review to be merged into future release (R5+).
Dataset
Observation
State
Actions
Task/Instructions
Episodes
Duration (hr)
Size TB
RGB (5x)
—
—
—
2030
11.3
0.5*
RGB (6x)
GPS/IMU
—
—
1000
5.5
0.67*
RGB (4x)
GPS/IMU
—
—
747
4.15
0.17*
RGB (1x)
GPS/IMU/CAN
☑️
—
1473
8.2
0.32*
RGB (1x)
GPS/IMU/CAN
☑️
—
2019
33
0.1
RGB (6x)
GPS/IMU/CAN
☑️
☑️
1000000
5000+
90+
Table 1: Open source self-driving datasets (*excluding lidar and radar). Source
L2D was collected with identical sensor suites installed on 60 EVs operated by driving schools in 30 German cities over the span of 3 years. The policies in L2D are divided into two groups — expert policies executed by driving instructors and student policies by learner drivers. Both the policy groups include natural language instructions for the driving task. For example, “When you have the right of way, take the third exit from the roundabout, carefully driving over the pedestrian crossing”.
Expert policy — Driving instructor
Student policy — Learner driver
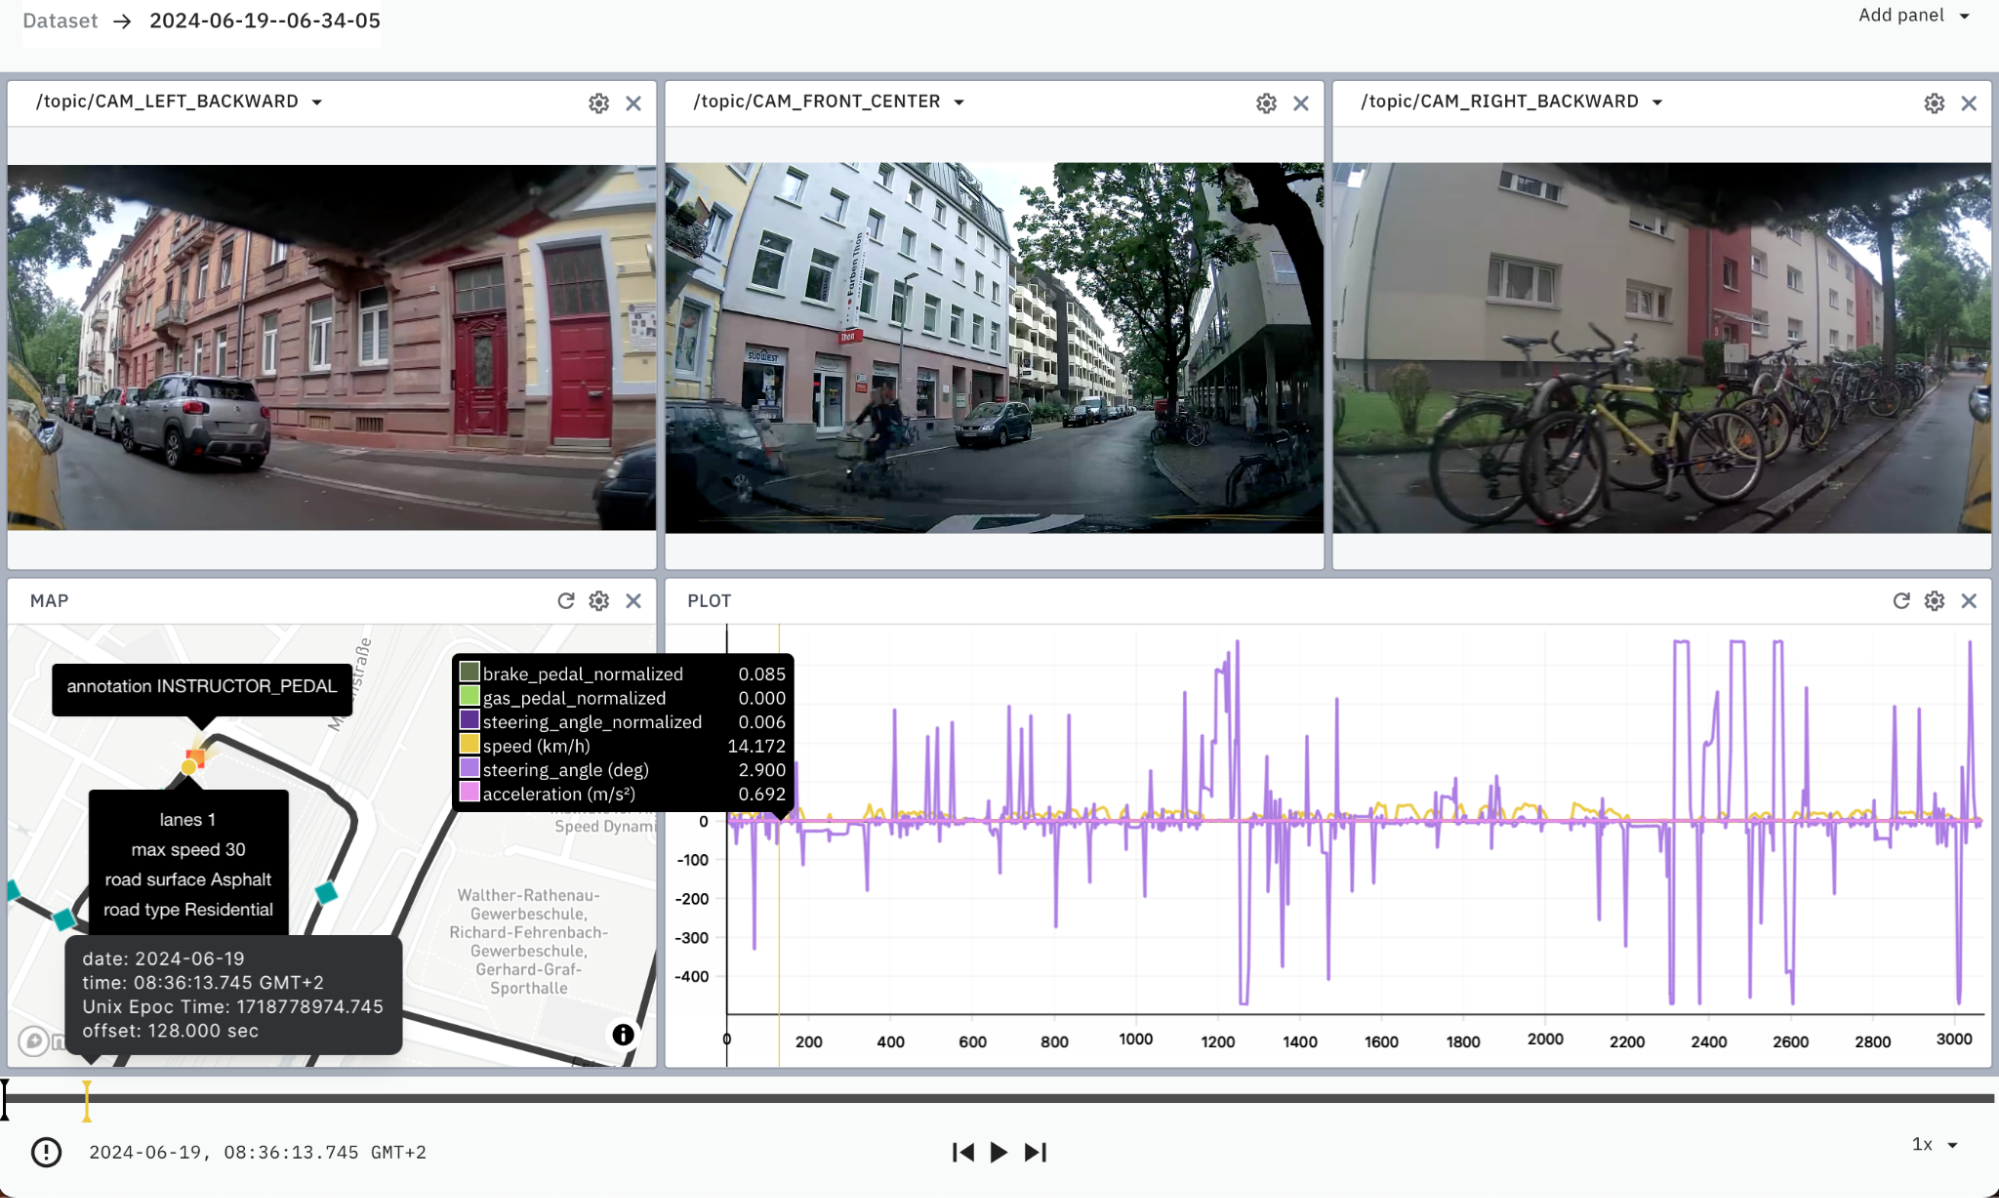
Fig 1: Visualization: Nutron (3 of 6 cameras shown for clarity) Instructions: “When you have the right of way, drive through the roundabout and take the third exit”.
Expert policies have zero driving mistakes and are considered as optimal, whereas student policies have known sub optimality (Fig 2).
Fig 2: Student policy with jerky steering to prevent going into lane of the incoming truck
Both groups cover all driving scenarios that are mandatory for completion to obtain a driving license within the EU (German version), for example, overtaking, roundabouts and train tracks. In the release (See below R3+), for suboptimal student policies, a natural language reasoning for sub-optimality will be included. F.ex “incorrect/jerky handling of the steering wheel in the proximity of in-coming traffic ” (Fig 2)
Expert: Driving Instructor
Student: Learner Driver
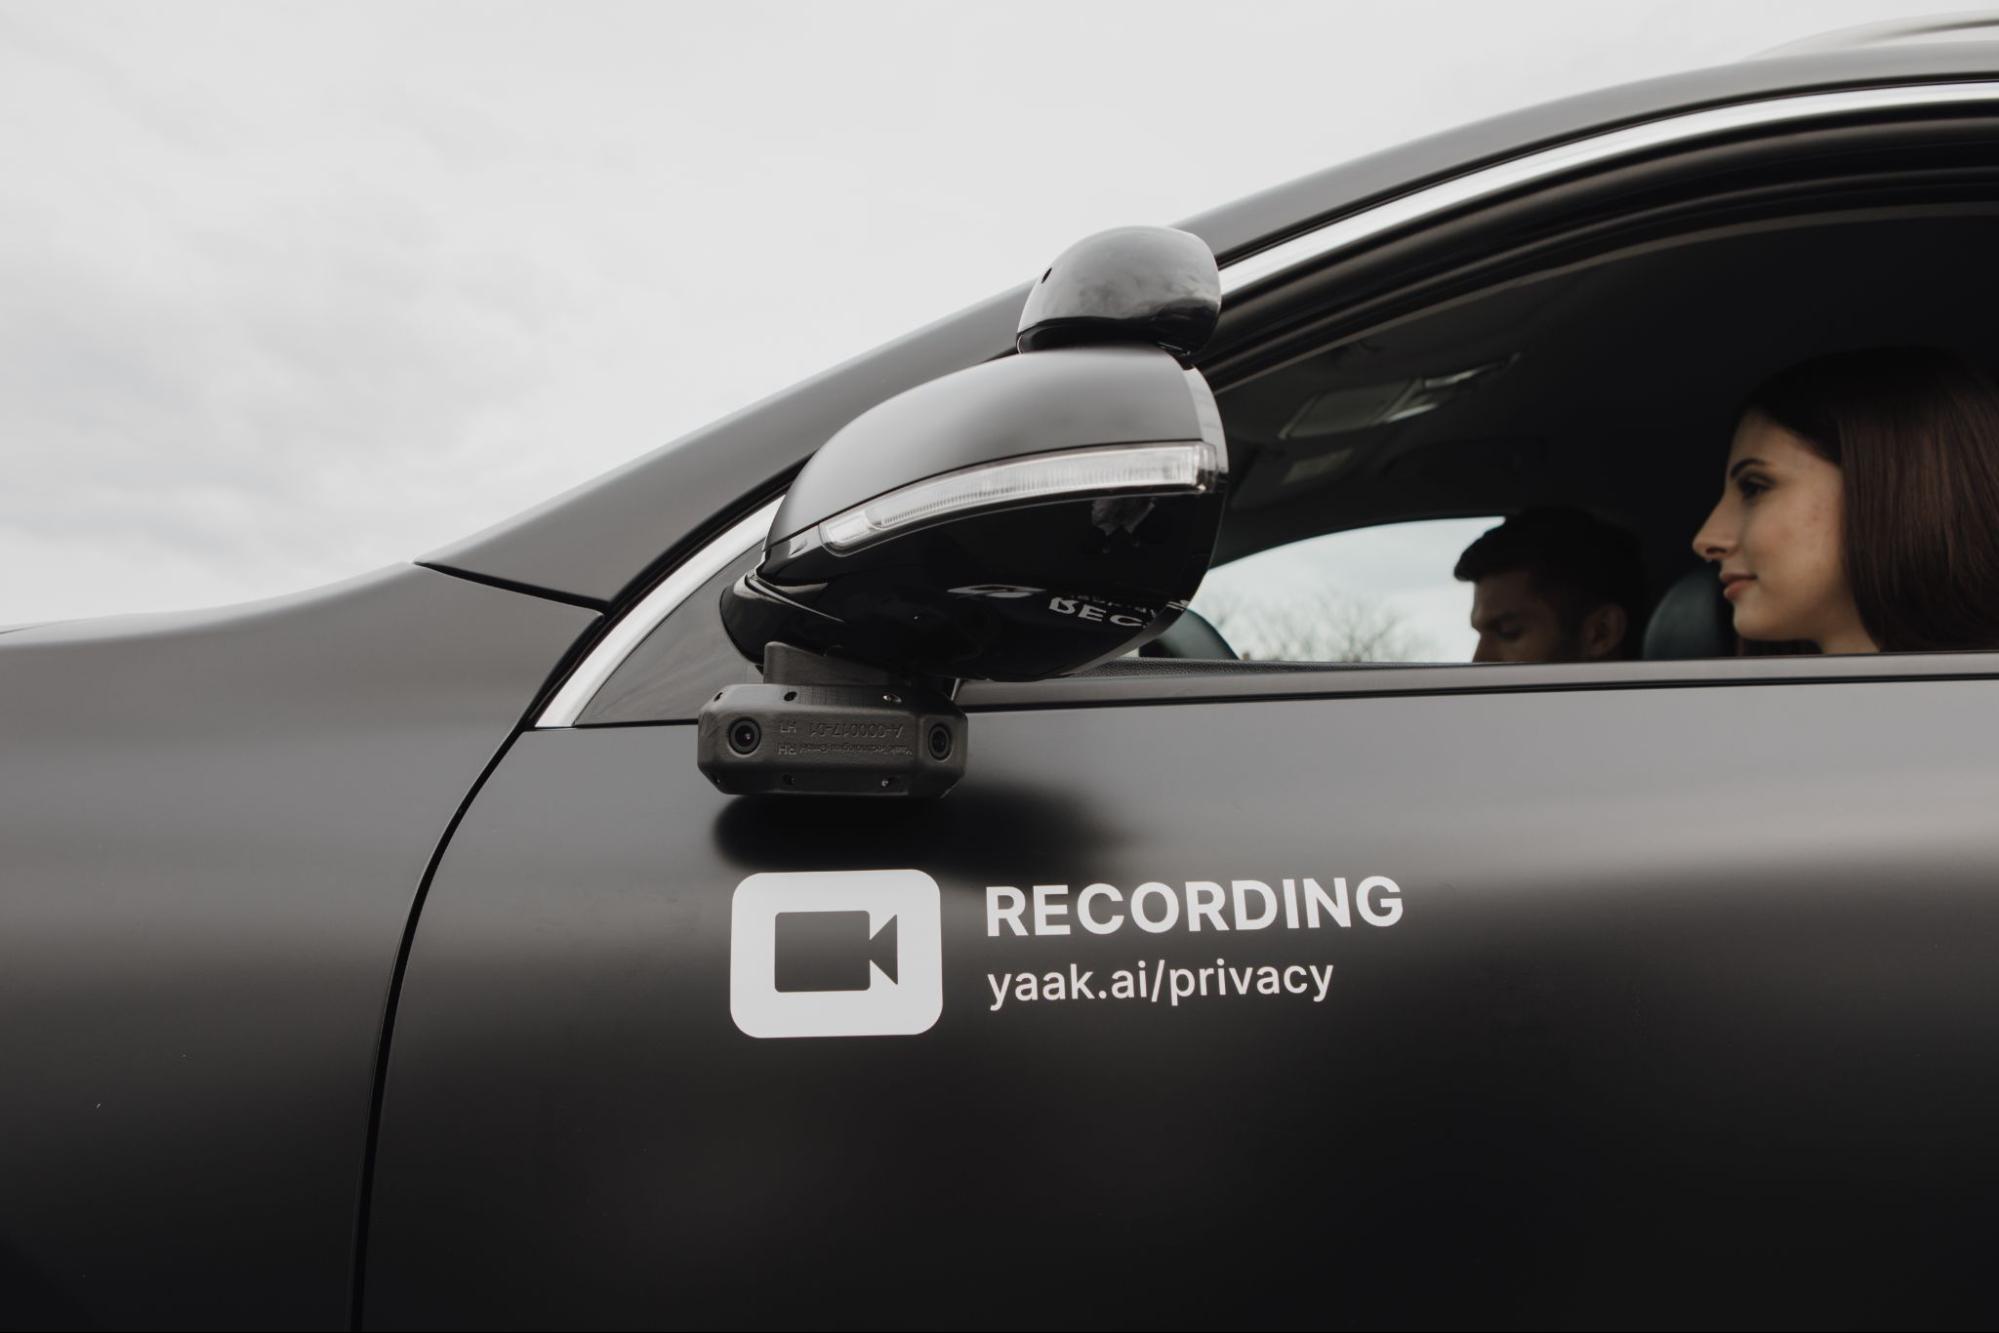
Expert policies are collected when driving instructors are operating the vehicle. The driving instructors have at least 10K+ hours of experience in teaching learner drivers. The expert policies group covers the same driving tasks as the student policies group.
Student policies are collected when learner drivers are operating the vehicle. Learner drivers have varying degrees of experience (10–50 hours). By design, learner drivers cover all EU-mandated driving tasks, from high-speed lane changes on highways to navigating narrow pedestrian zones.
L2D: Learning to Drive
L2D (R2+) aims to be the largest open-source self-driving dataset that empowers the AI community with unique and diverse ‘episodes’ for training end-to-end spatial intelligence. With the inclusion of a full spectrum of driving policies (student and experts), L2D captures the intricacies of safely operating a vehicle. To fully represent an operational self-driving fleet, we include episodes with diverse environment conditions, sensor failures, construction zones and non-functioning traffic signals.
Both the expert and student policy groups are captured with the identical sensor setup detailed in the table below. Six RGB cameras capture the vehicle’s context in 360o, and on-board GPS captures the vehicle location and heading. An IMU collects the vehicle dynamics, and we read speed, gas/brake pedal, steering angle, turn signal and gear from the vehicle’s CAN interface. We synchronized all modality types with the front left camera (observation.images.front_left) using their respective unix epoch timestamps. We also interpolated data points where feasible to enhance precision (See Table 2.) and finally reduced the sampling rate to 10 hz.
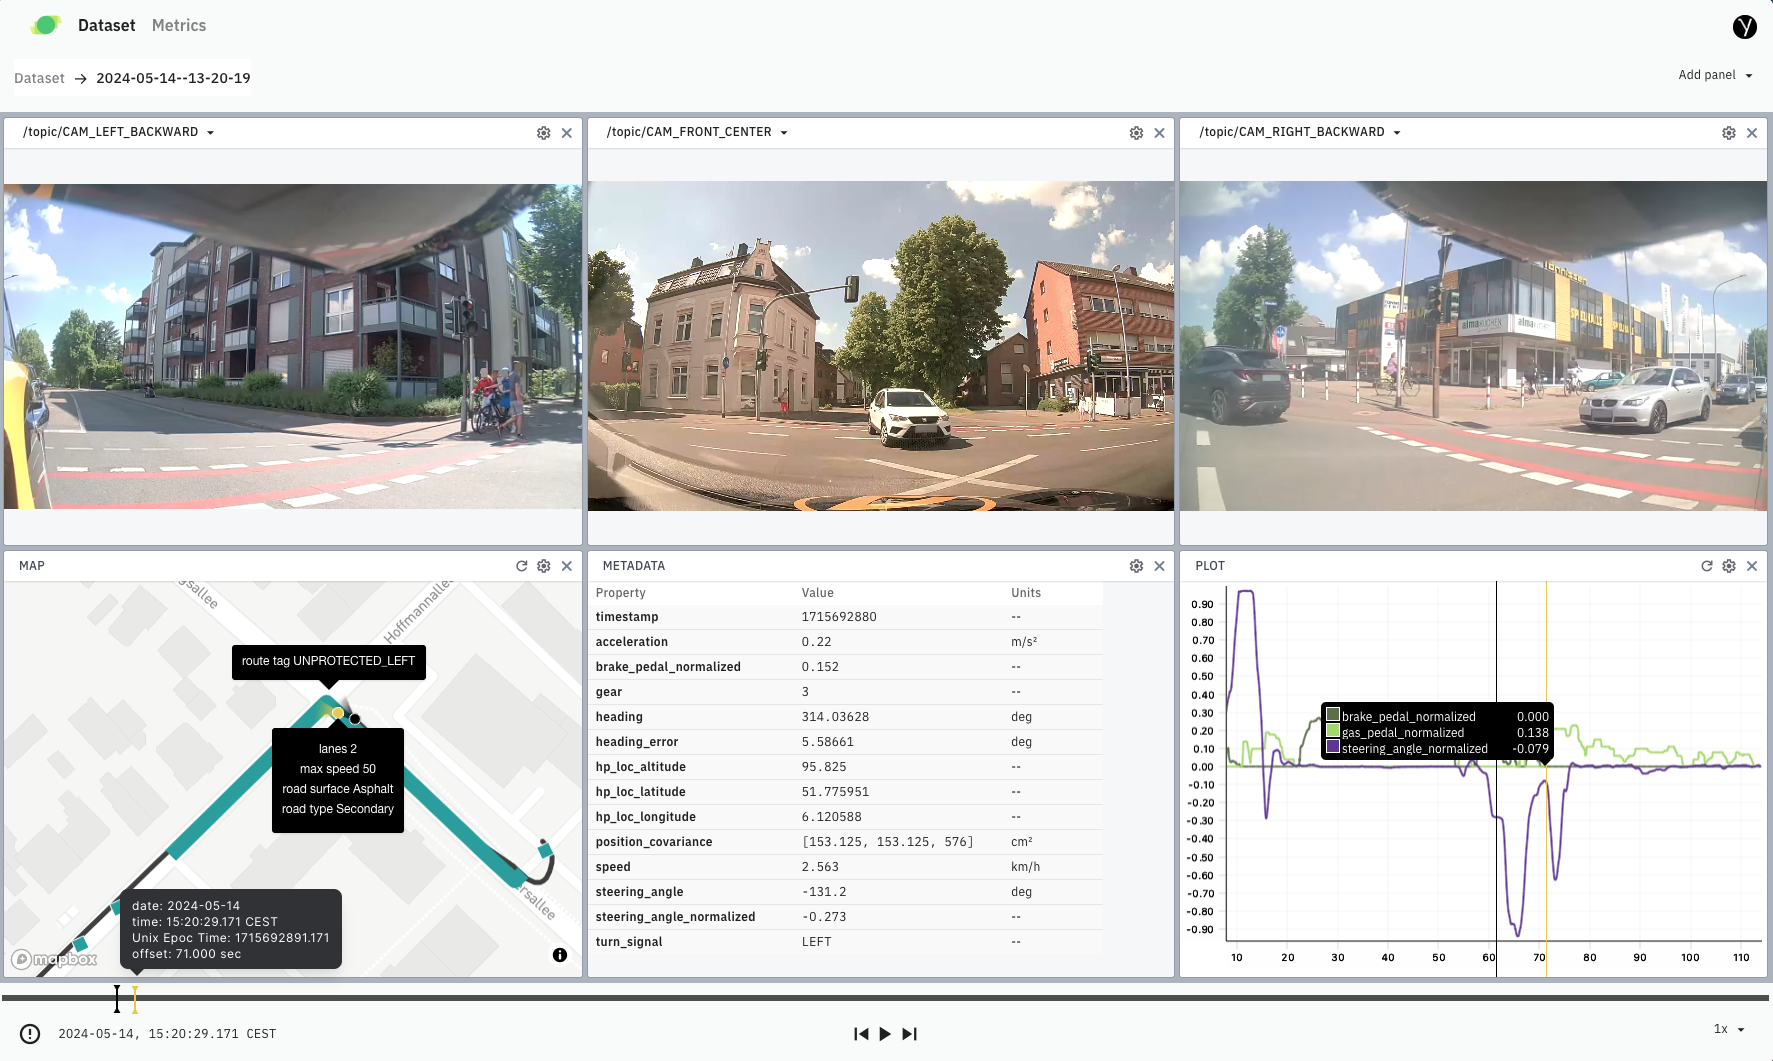
Fig 3: Multimodal data visualization with Visualization: Nutron (only 3 of 6 cameras shown for clarity)
Modality
LeRobotDataset v3.0 key
Shape
alignment[tol][strategy]
image (x6)
observation.images.front_left[left_forward,..]
N3HW
speed
observation.state.vehicle.speed
N1
heading
observation.state.vehicle.heading[heading_error]
N1
GPS
observation.state.vehicle.latitude[longitude/altitude]
N1
IMU
observation.state.vehicle.acceleration_x[y]
N1
waypoints
observation.state.vehicle.waypoints
N2L
timestamp
N1
observation.images.front_left
gas
action.continous.gas_pedal_normalized
N1
brake
action.continous.brake_pedal_normalized
N1
steering
action.continous.steering_angle_normalized
N1
turn signal
N1
gear
N1
language
N1
—
language
N1
—
lane count
N1
road type
N1
road surface
N1
max speed
N1
precipitation
observation.state.precipitation
N1
conditions
N1
lighting
N1
Table 2: Modality types, LeRobot v3.0 key, shape and interpolation strategy.
L2D follows the official German driving task catalog (detailed version) definition of driving tasks, driving sub-tasks and task definition. We assign a unique Task ID and natural language instructions to all episodes. The LeRobot:task for all episodes is set to “Follow the waypoints while adhering to traffic rules and regulations”. The table below shows a few sample episodes, their natural language instruction, driving tasks and subtasks. Both expert and student policies have an identical Task ID for similar scenarios, whereas the instructions vary with the episode.
Episode
Instructions
Driving task
Driving sub-task
Task Definition
Task ID
Visualization LeRobot Visualization Nutron
Drive straight through going around the parked delivery truck and yield to the incoming traffic
3 Passing, overtaking
3.1 Passing obstacles and narrow spots
This sub-task involves passing obstacles or navigating narrow roads while following priority rules.
3.1.1.3a Priority regulation without traffic signs (standard)
Visualization LeRobot Visualization Nutron
Drive through the unprotected left turn yielding to through traffic
4 Intersections, junctions, entering moving traffic
4.1 Crossing intersections & junctions
This sub-task involves crossing intersections and junctions while following priority rules and observing other traffic.
4.1.1.3a Right before left
Visualization LeRobot Visualization Nutron
Drive straight up to the yield sign and take first exit from the roundabout
5 Roundabouts
5.1 Roundabouts
This sub-task involves safely navigating roundabouts, understanding right-of-way rules, and positioning correctly.
5.1.1.3a With one lane
Table 3: Sample episodes in L2D, their instructions and Task ID derived from EU driving task catalog
We automate the construction of the instructions and waypoints using the vehicle position (GPS), Open-Source Routing Machine, OpenStreetMap and a Large Language Model (LLM) (See below). The natural language queries are constructed to closely follow the turn-by-turn navigation available in most GPS navigation devices. The waypoints (Fig 4) are computed by map-matching the raw GPS trace to the OSM graph and sampling 10 equidistant points (orange) spanning 100 meters from the vehicles current location (green), and serve as drive-by-waypoints.
Fig 4: L2D 6x RGB cameras, waypoints (orange) and vehicle location (green) Instructions: drive straight up to the stop stop sign and then when you have right of way, merge with the moving traffic from the left
Search & Curation
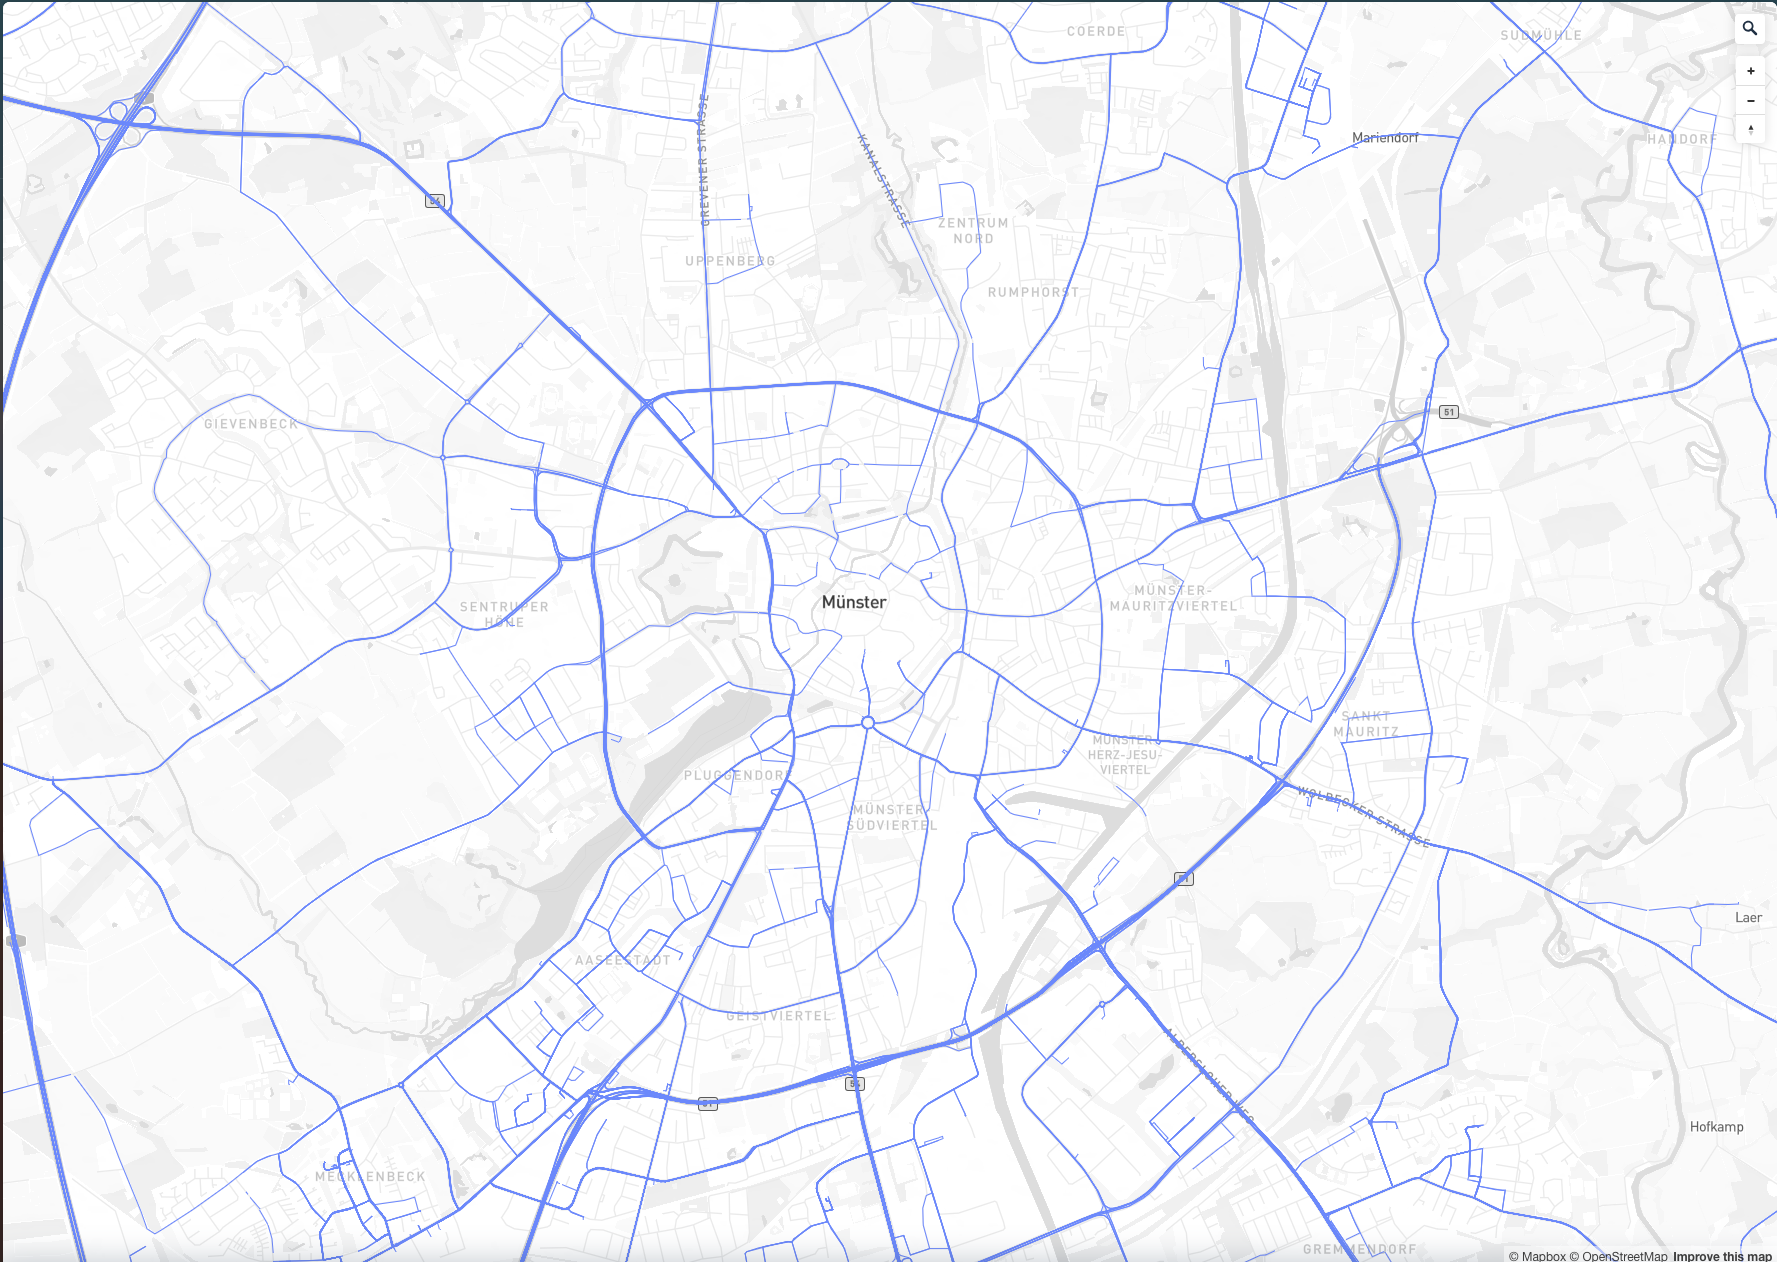
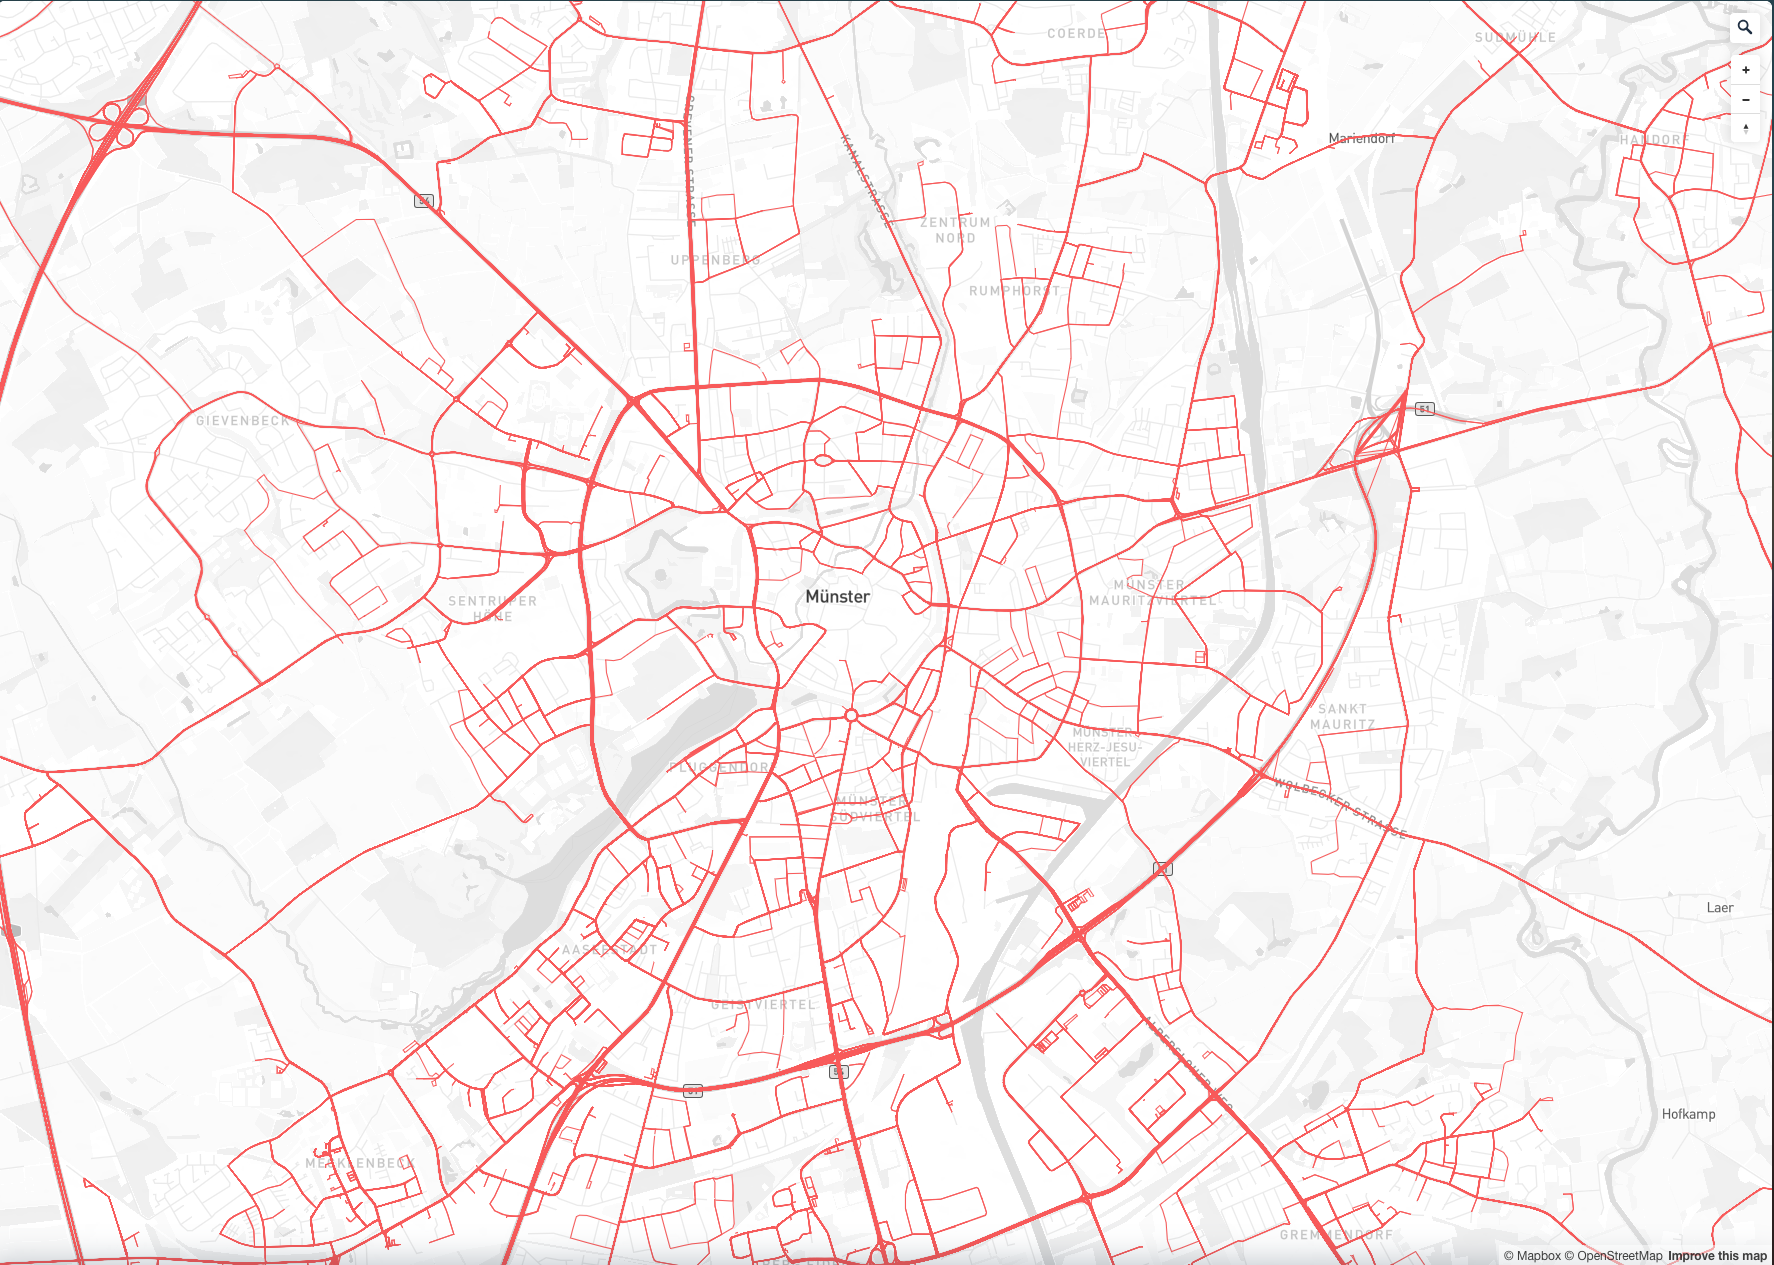
GPS traces from the expert policies collected from the driving school fleet. Click here to see the full extent of expert policies in L2D.
Student policies cover the same geographical locations as expert policies. Click here to see the full extent of student policies in L2D.
We collected the expert and student policies with a fleet of 60 KIA E-niro driving school vehicles operating in 30 German cities, with an identical sensor suite. The multimodal logs collected with the fleet are unstructured and void of any task or instructions information. To search and curate for episodes we enrich the raw multimodal logs with information extracted through map matching the GPS traces with OSRM and assigning node and way tags from OSM (See next section). Coupled with a LLM, this enrichment step enables searching for episodes through the natural language description of the task.
OpenStreetMap
For efficiently searching relevant episodes, we enrich the GPS traces with turn information obtained by map-matching the traces using OSRM. We additionally use the map-matched route and assign route features, route restrictions and route maneuvers, collectively referred to as route tasks, to the trajectory using OSM (See sample Map). Appendix A1-A2 provides for more details on the route tasks we assign to GPS traces.
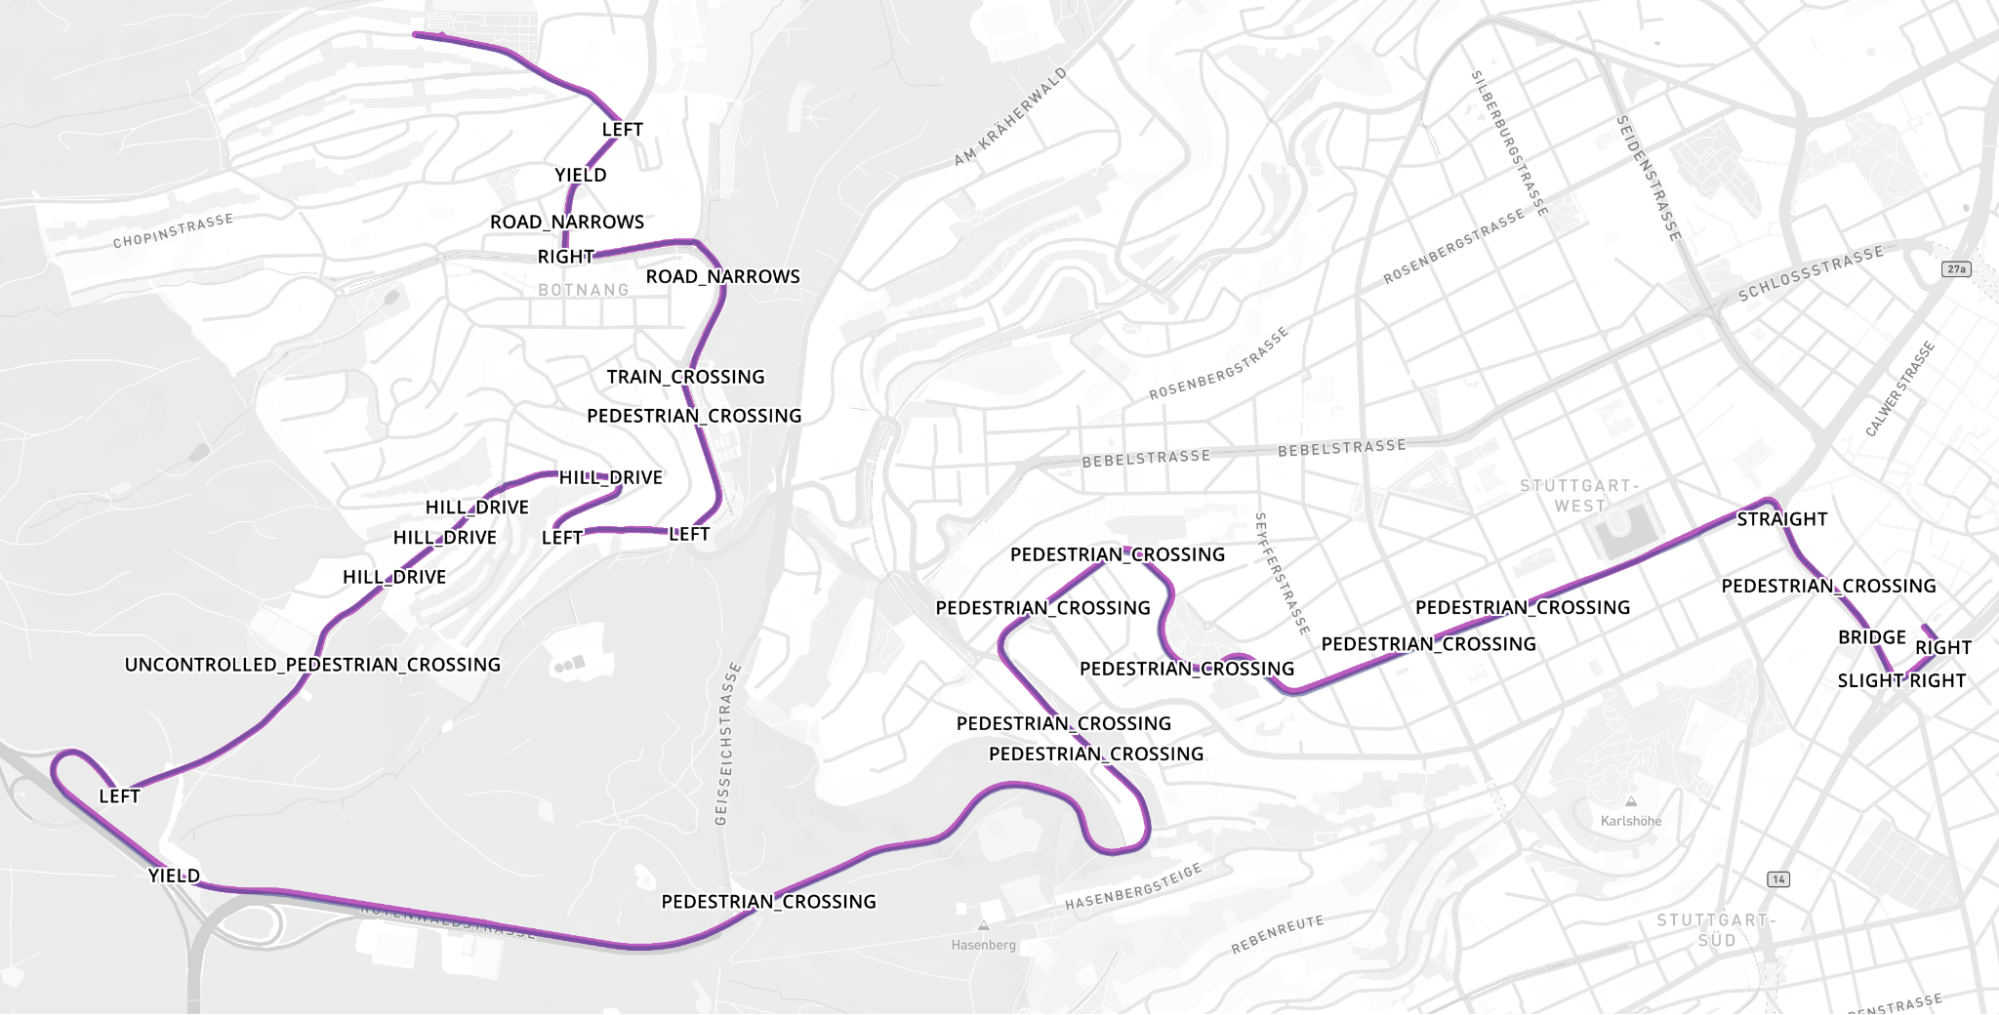
Fig 5: Driving tasks assigned to raw GPS trace (View map)
The route tasks which get assigned to the map-matched route, are assigned the beginning and end timestamps (unix epoch), which equates to the time when the vehicle enters and exits the geospatial linestring or point defined by the task (Fig 6).
Begin: Driving task (Best viewed in a separate tab)
End: Driving task (Best viewed in a separate tab)
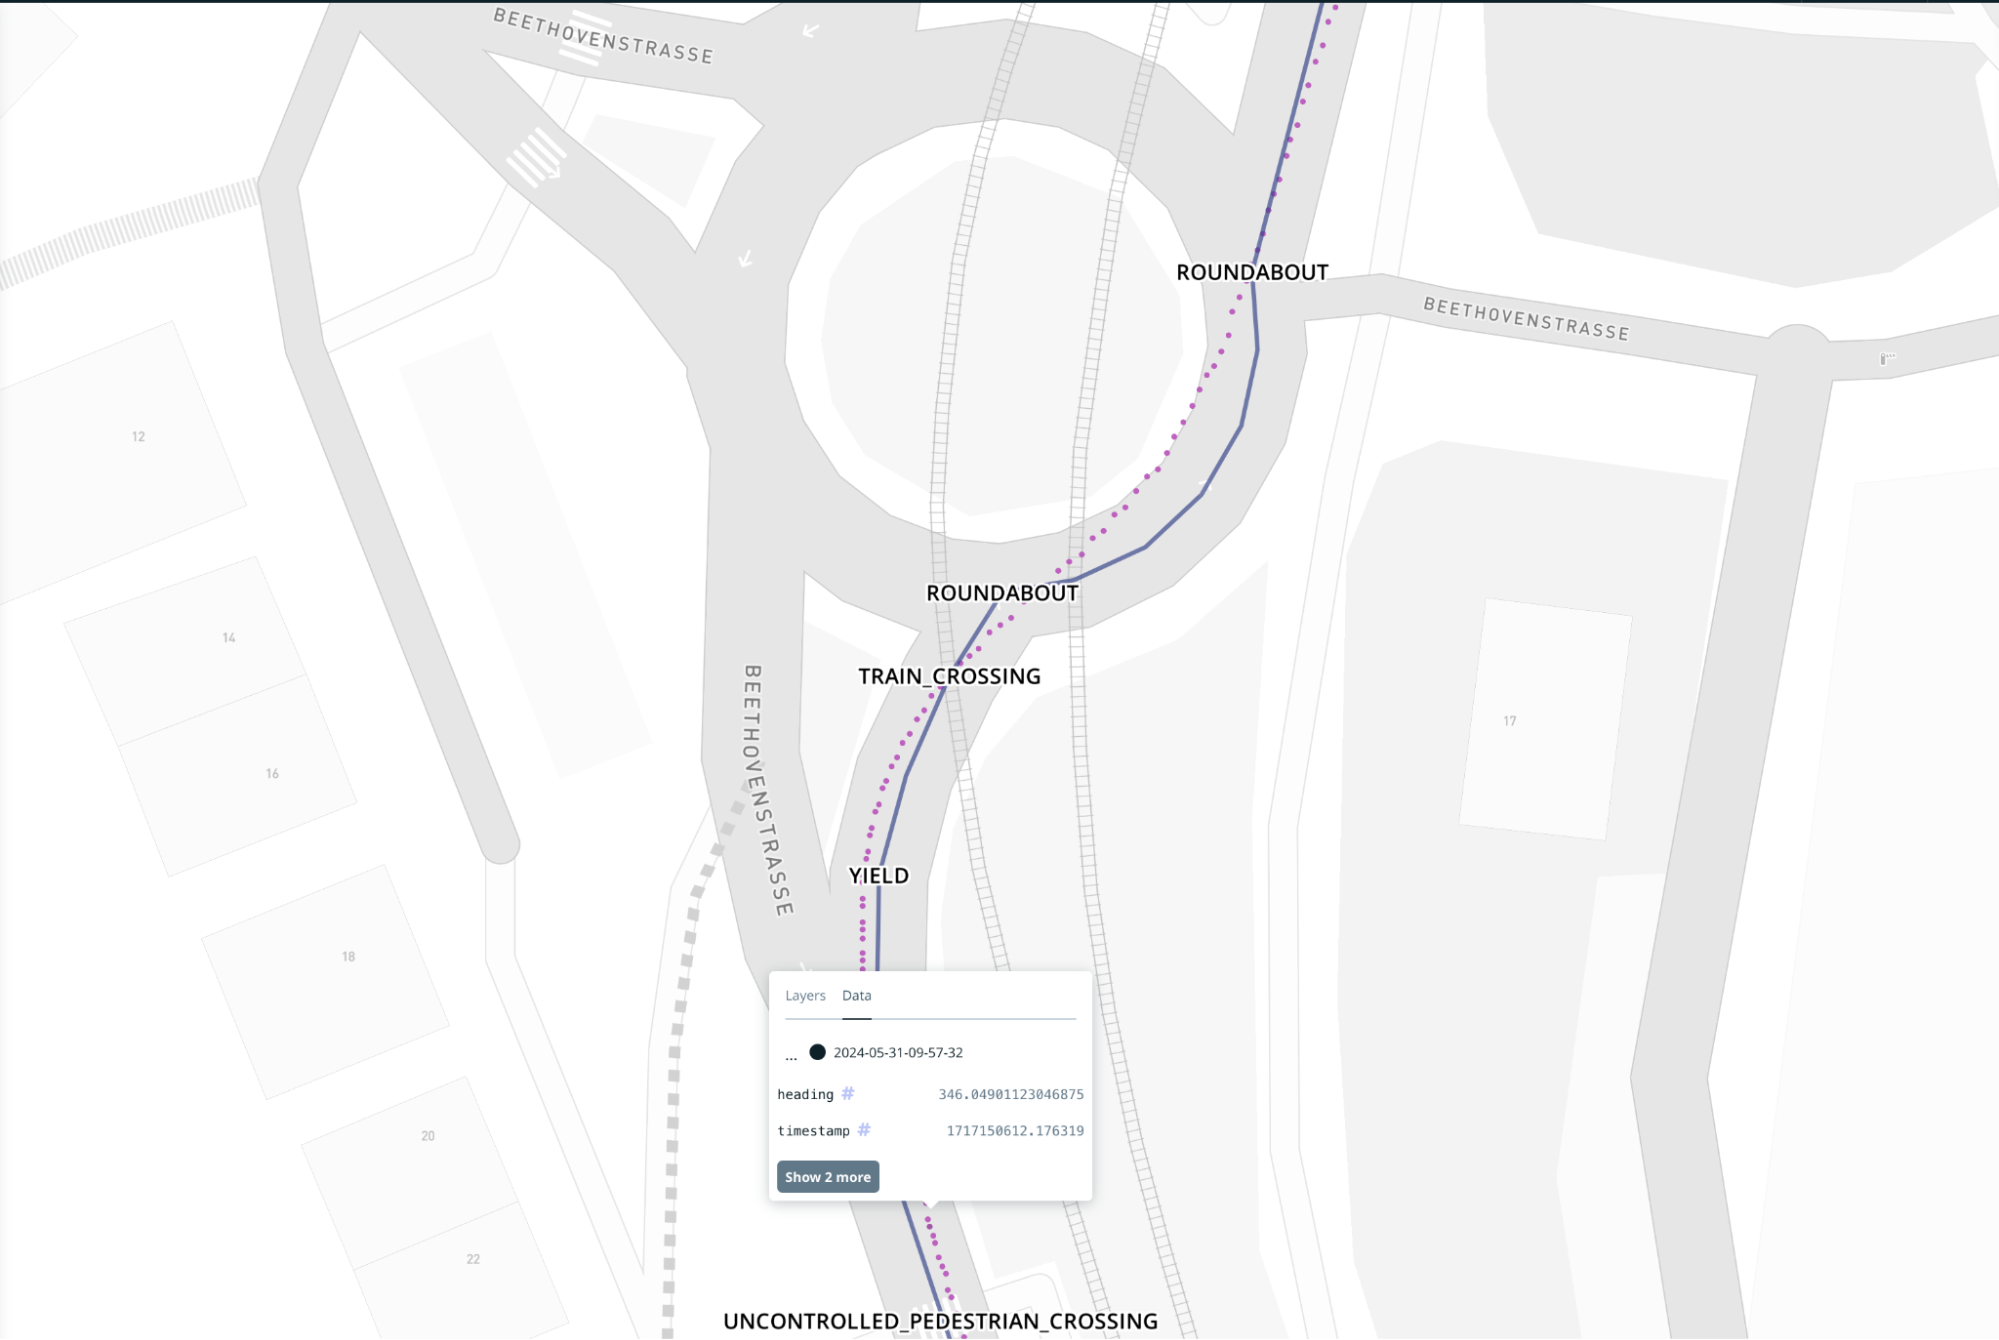
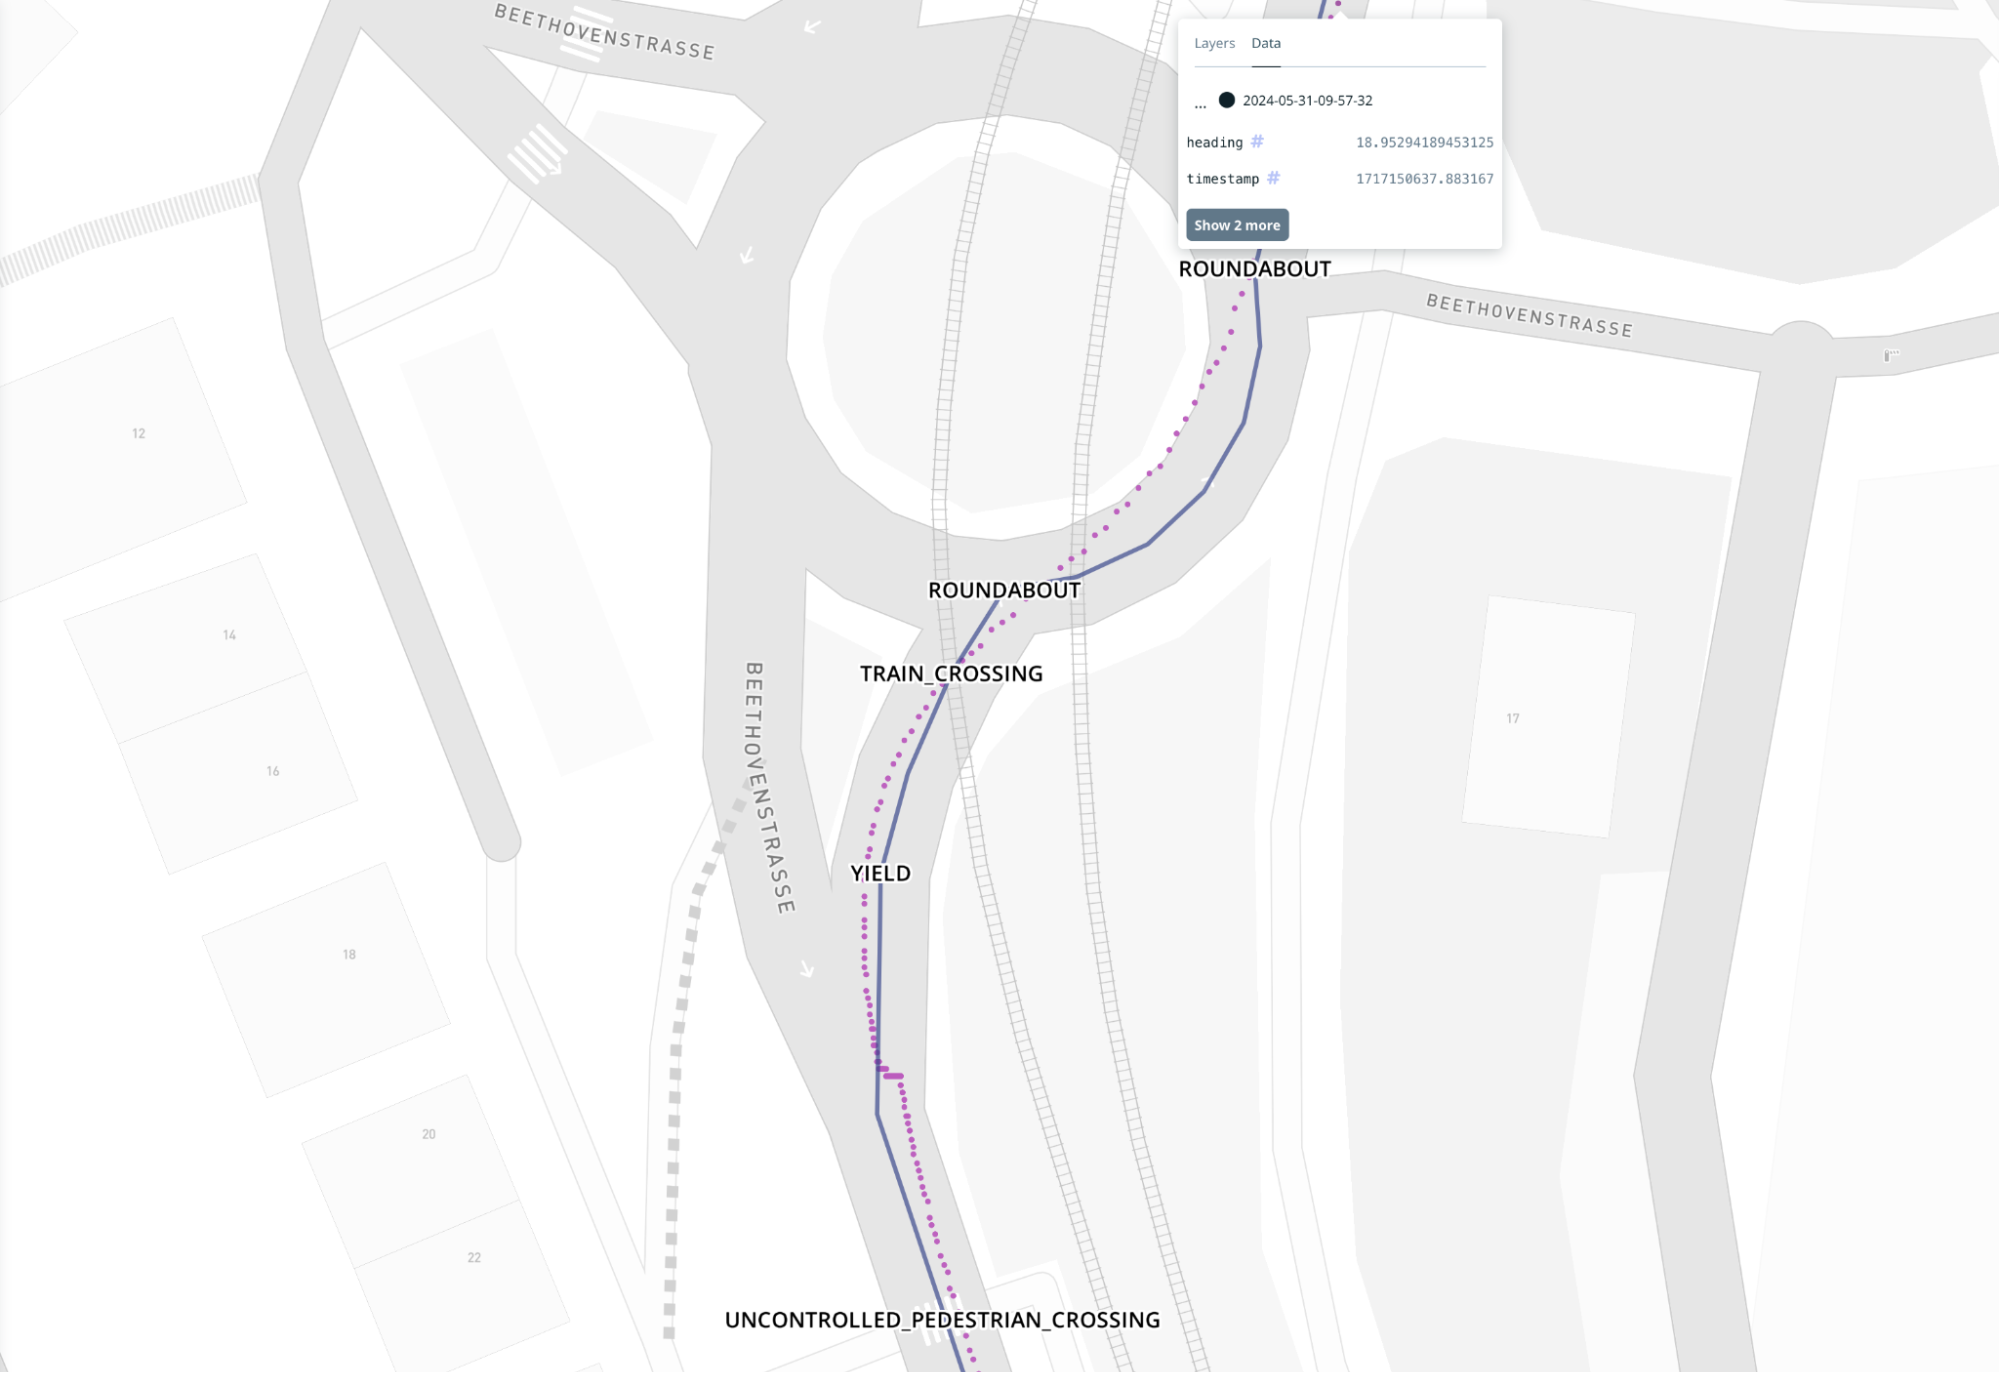
Fig 6: Pink: GNSS trace, Blue: Matched route, tasks: Yield, Train crossing and Roundabout (View Map)
Multimodal search
We perform semantic spatiotemporal indexing of our multimodal data with the route tasks as described in Fig 5. This step provides a rich semantic overview of our multimodal data. To search within the semantic space for representative episodes by instructions, for example, “drive up to the roundabout and when you have the right of way turn right”, we built a LLM-powered multimodal natural language search, to search within all our drive data (> 1 PetaBytes) and retrieve matching episodes.
We structured the natural language queries (instructions) to closely resemble turn-by-turn navigation available in GPS navigation devices. To translate instructions to route tasks, we prompt the LLM with the instructions and steer its output to a list of route features, route restrictions, route maneuvers and retrieve episodes assigned to these route tasks. We perform a strict validation of the output from the LLM with a pydantic model to minimize hallucinations. Specifically we use llama-3.3-70b and steer the output to the schema defined by the pydantic model. To further improve the quality of the structured output, we used approx 30 pairs of known natural language queries and route tasks for in-context learning. Appendix A. 2 provides details on the in-context learning pairs we used.
Instructions: Drive up to the roundabout and when you have the right of way turn right
LeRobot
L2D on 🤗 is converted to LeRobotDataset v2.1 and LeRobotDataset v3.0 format to fully leverage the current and future models supported within LeRobot. The AI community can now build end-to-end self-driving models leveraging the state-of-the-art imitation learning and reinforcement learning models for real world robotics like ACT, Diffusion Policy, and Pi0.
Existing self-driving datasets (table below) focus on intermediate perception and planning tasks like 2D/3D object detection, tracking, segmentation and motion planning, which require high quality annotations making them difficult to scale. Instead L2D is focused on the development of end-to-end learning which learns to predict actions (policy) directly from sensor input (Table 1.). These models leverage internet pre-trained VLM and VLAM.
Releases
Robotics AI models’ performances are bounded by the quality of the episodes within the training set. To ensure the highest quality episodes, we plan a phased release for L2D. With each new release we add additional information about the episodes. Each release R1+ is a superset of the previous releases to ensure clean episode history.
instructions: Natural language instruction of the driving task 2. task_id: Mapping of episodes to EU mandated driving tasks Task ID 3. observation.state.route : Information about lane count, turn lanes from OSM 4. suboptimal: Natural language description for the cause of sub-optimal policies
HF
Nutron
Date
Episodes
Duration
Size
instructions
task_id
observation.state.route
suboptimal
March 2025
100
0.5+ hr
9,5 GB
☑️
April 2025
1K
5+ hr
95 GB
☑️
May 2025
10K
50+ hr
0.5 TB
☑️
☑️
☑️
Sept 2025
100K
500+ hr
5 TB
☑️
☑️
☑️
R4
R4
Nov 2025
1M
5000+ hr
90 TB
☑️
☑️
☑️
☑️
Table 5: L2D release dates
The entire multimodal dataset collected by Yaak with the driving school fleet is 5x larger than the planned release. To further the growth of L2D beyond R4, we invite the AI community to search and uncover scenarios within our entire data collection and build a community powered open-source L2D. The AI community can now search for episodes through our natural language search and queue their collection for review by the community for merging them into the upcoming releases. With L2D, we hope to unlock an ImageNet moment for spatial intelligence.
Fig 7: Searching episodes by natural language instructions
Using L2D with HF/LeRobot
For R0, R1 we recommend using LeRobotDataset, with revision=[R0|R1], which can be used directly from the pypi release of LeRobot. For R2+, please follow installation outlined here or install from main as below, as we recommend using StreamingLeRobotDataset as R3 is is Dataset v3.0 format.
# uv for python deps
curl -LsSf https://astral.sh/uv/install.sh | sh
# install python version and pin it
uv init && uv python install 3.12.4 && uv python pin 3.12.4
# add lerobot to deps for R0, R1
uv add lerobot
# for R2+
GIT_LFS_SKIP_SMUDGE=1 uv add "git+https://github.com/huggingface/lerobot.git@main"
uv run python
>>> from lerobot.datasets.streaming_dataset import StreamingLeRobotDataset
# This will load 3 episodes=[0, 9999, 99999], to load all the episodes please remove it
>>> dataset = StreamingLeRobotDataset("yaak-ai/L2D", episodes=[0, 9999, 99999], streaming=True, buffer_size=1000)
>>> dataset.meta
LeRobotDatasetMetadata({
    Repository ID: 'yaak-ai/L2D',
    Total episodes: '100000',
    Total frames: '19042712',
    Features: '['observation.state.vehicle', 'observation.state.lanes', 'observation.state.road', 'observation.state.surface', 'observation.state.max_speed', 'observation.state.precipitation', 'observation.state.conditions', 'observation.state.lighting', 'observation.state.waypoints', 'observation.state.timestamp', 'task.policy', 'task.instructions', 'action.continuous', 'action.discrete', 'timestamp', 'frame_index', 'episode_index', 'index', 'task_index', 'observation.images.left_forward', 'observation.images.front_left', 'observation.images.right_forward', 'observation.images.left_backward', 'observation.images.rear', 'observation.images.right_backward', 'observation.images.map']',
})',
Closed Loop Testing
LeRobot driver
For real world testing of the AI models trained with L2D and LeRobot, we invite the AI community to submit models for closed loop testing with a safety driver, starting summer of 2025. The AI community will be able to queue their models for closed loop testing, on our fleet and choose the tasks they’d like the model to be evaluated on and, for example, navigating roundabouts or parking. The model would run in inference mode (Jetson AGX or similar) on-board the vehicle. The models will drive the vehicle with LeRobot driver in two modes
drive-by-waypoints: “Follow the waypoints adhering to driving rules and regulations” given observation.state.vehicle.waypoints
drive-by-language: “Drive straight and turn right at the pedestrian crossing”
Additional Resources
Driving task catalog (Fahraufgabenkatalog)
References
@article{yaak2023novel,
    author = {Yaak team},
    title ={A novel test for autonomy},
    journal = {https://www.yaak.ai/blog/a-novel-test-for-autonomy},
    year = {2023},
}
@article{yaak2023actiongpt,
    author = {Yaak team},
    title ={Next action prediction with GPTs},
    journal = {https://www.yaak.ai/blog/next-action-prediction-with-gpts},
    year = {2023},
}
@article{yaak2024si-01,
    author = {Yaak team},
    title ={Building spatial intelligence part - 1},
    journal = {https://www.yaak.ai/blog/buildling-spatial-intelligence-part1},
    year = {2024},
}
@article{yaak2024si-01,
    author = {Yaak team},
    title ={Building spatial intelligence part - 2},
    journal = {https://www.yaak.ai/blog/building-spatial-intelligence-part-2},
    year = {2024},
}
Appendix
A.1 Route tasks
List of route restrictions. We consider route tags from OSM a restriction if it imposes restrictions on the policy, for example speed limit, yield or construction. Route features are physical structures along the route, for example inclines, tunnels and pedestrian crossing. Route maneuvers are different scenarios which a driver encounters during a normal operation of the vehicle in an urban environment, for example, multilane left turns and roundabouts.
Type
Name
Assignment
Task ID
Release
Route restriction
CONSTRUCTION
VLM
R1
Route restriction
CROSS_TRAFFIC
VLM
4.3.1.3a, 4.3.1.3b, 4.3.1.3d, 4.2.1.3a, 4.2.1.3b, 4.2.1.3d
R2
Route restriction
INCOMING_TRAFFIC
VLM
R2
Route restriction
OSM
R0
Route restriction
OSM
R0
Route restriction
LOW_SPEED_REGION (5, 10, 20 kph)
OSM
R0
Route restriction
OSM
3.2.1.3b
R0
Route restriction
PEDESTRIANS
VLM
7.2.1.3b
R1
Route restriction
OSM
3.1.1.3b
R0
Route restriction
OSM
R0
Route restriction
OSM
4.1.1.3b, 4.2.1.3b, 4.3.1.3b
R0
Route restriction
OSM
4.1.1.3b, 4.2.1.3b, 4.3.1.3b
R0
Route feature
OSM
R0
Route feature
CURVED_ROAD
OSM (derived)
2.1.1.3a, 2.1.1.3b
R0
Route feature
OSM
7.1.1.3a
R0
Route feature
OSM
R0
Route feature
OSM
R0
Route feature
NARROW_ROAD
VLM
Route feature
PARKING
OSM
R0
Route feature
OSM
7.2.1.3b
R0
Route feature
OSM
R0
Route feature
OSM
6.1.1.3a, 6.1.1.3b
R0
Route feature
OSM
6.2.1.3a
R0
Route feature
OSM
R0
Route feature
UNCONTROLLED_PEDESTRIAN_CROSSING
OSM
7.2.1.3b
R0
Route maneuver
ENTERING_MOVING_TRAFFIC
OSM (derived)
4.4.1.3a
R0
Route maneuver
CUTIN
VLM
R3
Route maneuver
LANE_CHANGE
VLM
1.3.1.3a, 1.3.1.3b
R3
Route maneuver
OSM
1.1.1.3a, 1.1.1.3b, 1.1.1.3c, 1.2.1.3a, 1.2.1.3b, 1.2.1.3c
R0
Route maneuver
OSM (derived)
4.3.1.3b, 4.3.1.3c, 4.3.1.3d
R0
Route maneuver
OSM (derived)
4.2.1.3b, 4.2.1.3c, 4.2.1.3d
R0
Route maneuver
PROTECTED_LEFT
OSM (derived)
4.3.1.3c, 4.3.1.3d
R0
Route maneuver
PROTECTED_RIGHT_WITH_BIKE
OSM (derived)
4.2.1.3c, 4.2.1.3d
R0
Route maneuver
RIGHT_BEFORE_LEFT
OSM (derived)
4.1.1.3a, 4.2.1.3a, 4.3.1.3a
R0
Route maneuver
OSM
4.2.1.3c
R0
Route maneuver
OSM
5.1.1.3a, 5.1.1.3b
R0
Route maneuver
STRAIGHT
OSM (derived)
8.1.1.3a
R0
Route maneuver
OVER_TAKE
VLM
3.2.1.3a, 3.2.1.3b
R4
Route maneuver
UNPROTECTED_LEFT
OSM (derived)
4.3.1.3a, 4.3.1.3b
R0
Route maneuver
OSM
4.2.1.3a, 4.2.1.3b
R0
OSM = Openstreetmap, VLM= Vision Language Model, derived: Hand crafted rules with OSM data
A.2 LLM prompts
Prompt template and pseudo code for configuring the LLM using groq to parse natural language queries into structured prediction for route features, restrictions and maneuvers with a pydantic model. The natural language queries are constructed to closely follow the turn-by-turn navigation available in most GPS navigation devices.
prompt_template: "You are parsing natural language driving instructions into PyDantic Model's output=model_dump_json(exclude_none=True) as JSON. Here are a few example pairs of instructions and structured output: {examples}. Based on these examples parse the instructions. The JSON must use the schema: {schema}"
groq:
model: llama-3.3-70b-versatile
temperature: 0.0
seed: 1334
response_format: json_object
max_sequence_len: 60000
Example pairs (showing 3 / 30) for in-context learning to steer the structured prediction of LLM, where ParsedInstructionModel is a pydantic model.
PROMPT_PAIRS = [
(
            "Its snowing. Go straight through the intersection, following the right before left rule at unmarked intersection",
        ParsedInstructionModel(
            	eventSequence=[
                    EventType(speed=FloatValue(value=10.0, operator="LT", unit="kph")),
                EventType(osmRouteManeuver="RIGHT_BEFORE_LEFT"),
                		EventType(speed=FloatValue(value=25.0, operator="LT", unit="kph")),
            	],
            turnSignal="OFF",
            weatherCondition="Snow",
        ),
        ),
(
            "stop at the stop sign, give way to the traffic and then turn right",
        ParsedInstructionModel(
            eventSequence=[
                	EventType(osmRouteRestriction="STOP"),
                EventType(turnSignal="RIGHT"),
                	EventType(speed=FloatValue(value=5.0, operator="LT", unit="kph")),
                EventType(osmRouteManeuver="RIGHT"),
            ],
            ),
    ),
    (
            "parking on a hill in the rain on a two lane road",
        ParsedInstructionModel(
            	osmLaneCount=[IntValue(value=2, operator="EQ")],
                osmRouteFeature=["PARKING", "HILL_DRIVE"],
            weatherCondition="Rain",
            ),
    ),
]

EXAMPLES = ""
for idx, (instructions, parsed) in enumerate(PROMPT_PAIRS):
    parsed_json = parsed.model_dump_json(exclude_none=True)
    update = f"instructions: {instructions.lower()} output: {parsed_json}"
    EXAMPLES += update

from groq import Groq
client = Groq(api_key=os.environ.get("GROQ_API_KEY"))

chat_completion = client.chat.completions.create(
                messages=[
                    {
                        "role": "system",
                        "content": prompt_template.format(examples=EXAMPLES, schema=json.dumps(ParsedInstructionModel.model_json_schema(), indent=2))
                    },
                    {
                        "role": "user",
                        "content": f"instructions : its daytime. drive to the traffic lights and when it turns green make a left turn",
                    },
                ],
                model=config["groq"]["model"],
                temperature=config["groq"]['temperature'],
                stream=False,
                seed=config["groq"]['seed'],
                response_format={"type": config['groq']['response_format']},
            )

            parsed_obj = ParsedInstructionModel.model_validate_json(chat_completion.choices[0].message.content)
            parsed_obj = parsed_obj.model_dump(exclude_none=True)
A.2 Data collection hardware
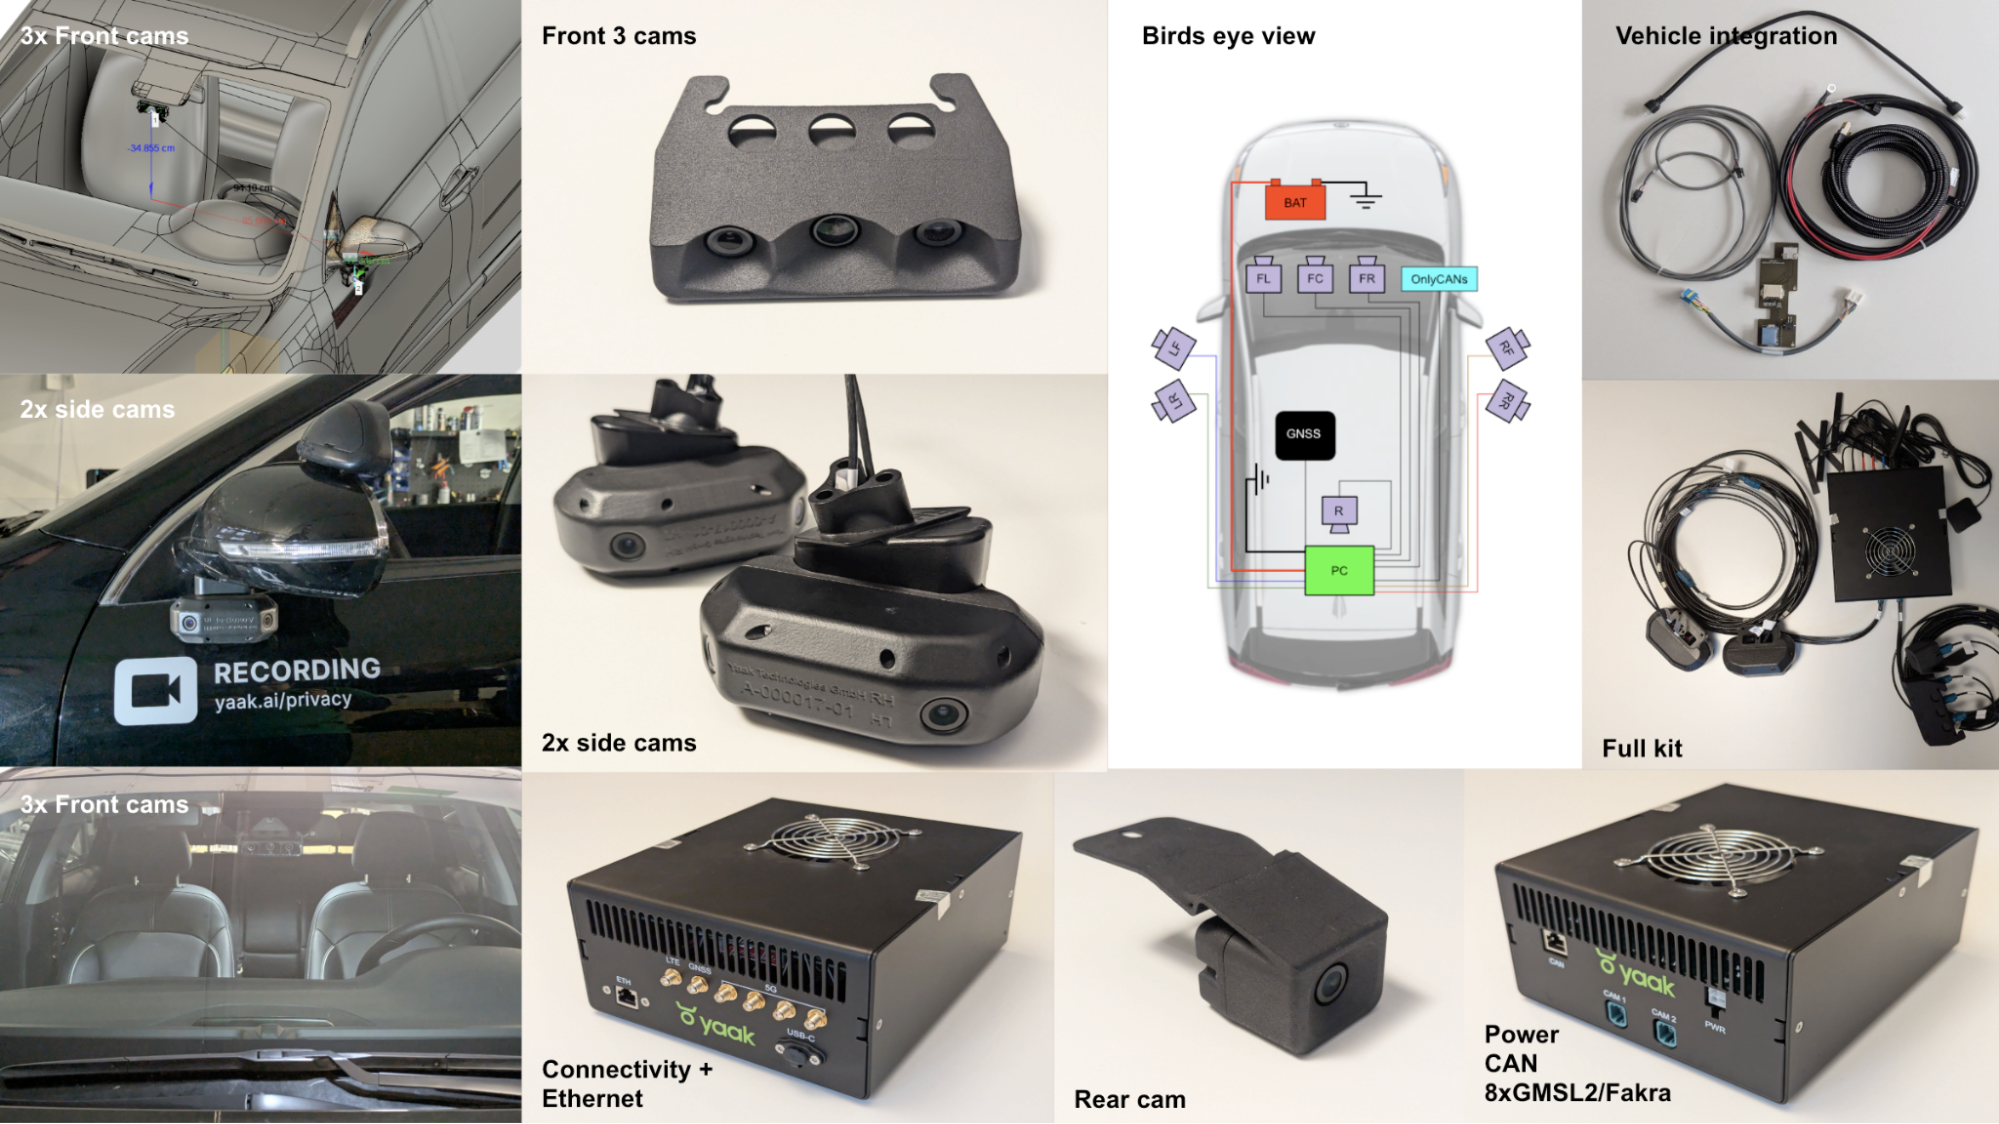
Onboard compute: NVIDIA Jetson AGX Xavier
8 cores @ 2/2.2 GHz, 16/64 GB DDR5
100 TOPS , 8 lanes MIPI CSI-2 D-PHY 2.1 (up to 20Gbps)
8x 1080p30 video encoder (H.265)
Power: 10-15V DC input, ~90W power consumption
Storage: SSD M.2 (4gen PCIe 1x4)
Video input 8 cameras:
2x Fakra MATE-AX with 4x GMSL2 with Power-over-Coax support
Onboard compute: Connectivity
Multi-band, Centimeter-level accuracy RTK module
5G connectivity: M.2 USB3 module with maximum downlink rates of 3.5Gbps and uplink rates of 900Mbps, dual SIM
Component
Vendor
Specs
RGB: Camera
RGB: Rugged Camera
5
GNSS
5G antenna
NVIDIA Jetson Orin NX - 64 GB
Nvidia
Table 6: Information on hardware kit used for data collection